RAG for Business in 2026: Build an AI Assistant Your Team Can Trust
The answer may already exist somewhere in your organisation – tucked away in your company’s onboarding document, in your company’s product page, in one of your old support cases, or perhaps buried deep down in a folder that only one experienced employee knows how to navigate. A customer comes up with a simple question, and you spend twenty minutes looking for the right answer. And there you go: here's your initial approach at business AI – you are dealing with a repeated information problem and a source you can verify.
Retrieval-augmented generation (RAG) ties your application to particular sources of information. It uses the relevant information to generate the response. This is how you can increase your support assistant’s or internal knowledge base’s efficiency even if it doesn’t guarantee that all the answers provided will be correct and all documents suitable for distribution.
For corporations developing their AI chatbots in 2026, much of the important work extends beyond the model: data quality, access permissions, evaluation, escalation, and ongoing ownership. This guide will explain how to create a RAG assistant beneficial for a particular corporation, how to test it, and what to ask from your implementation partner.
Identify a challenge that has an answer you can confirm
First, develop a concise workflow. The assistant that is expected to provide the specifications of a product according to the company’s approval is simpler to test than a chatbot that knows everything about the company. The assistant that is aimed at supporting customers within a certain product line is simpler to manage than the one with years of contradictory policies.
Gather a list of questions that are frequently asked by people. It contains easy, ambiguous questions and questions where a human has to make a choice. Ask those employees who answer such questions about their sources. If there is no agreement among them on how to respond to such questions, the AI system will not resolve organisational conflicts just by analyzing additional documents.
Determine the cost of being wrong. Being wrong about the office working hours would be an inconvenience while being wrong about a money refund would cause a business conflict. More critical subjects require stricter control and a clearly defined escalation policy. Set the conditions for where the assistant answers, quotes or refers to a person.
Know how the RAG process works
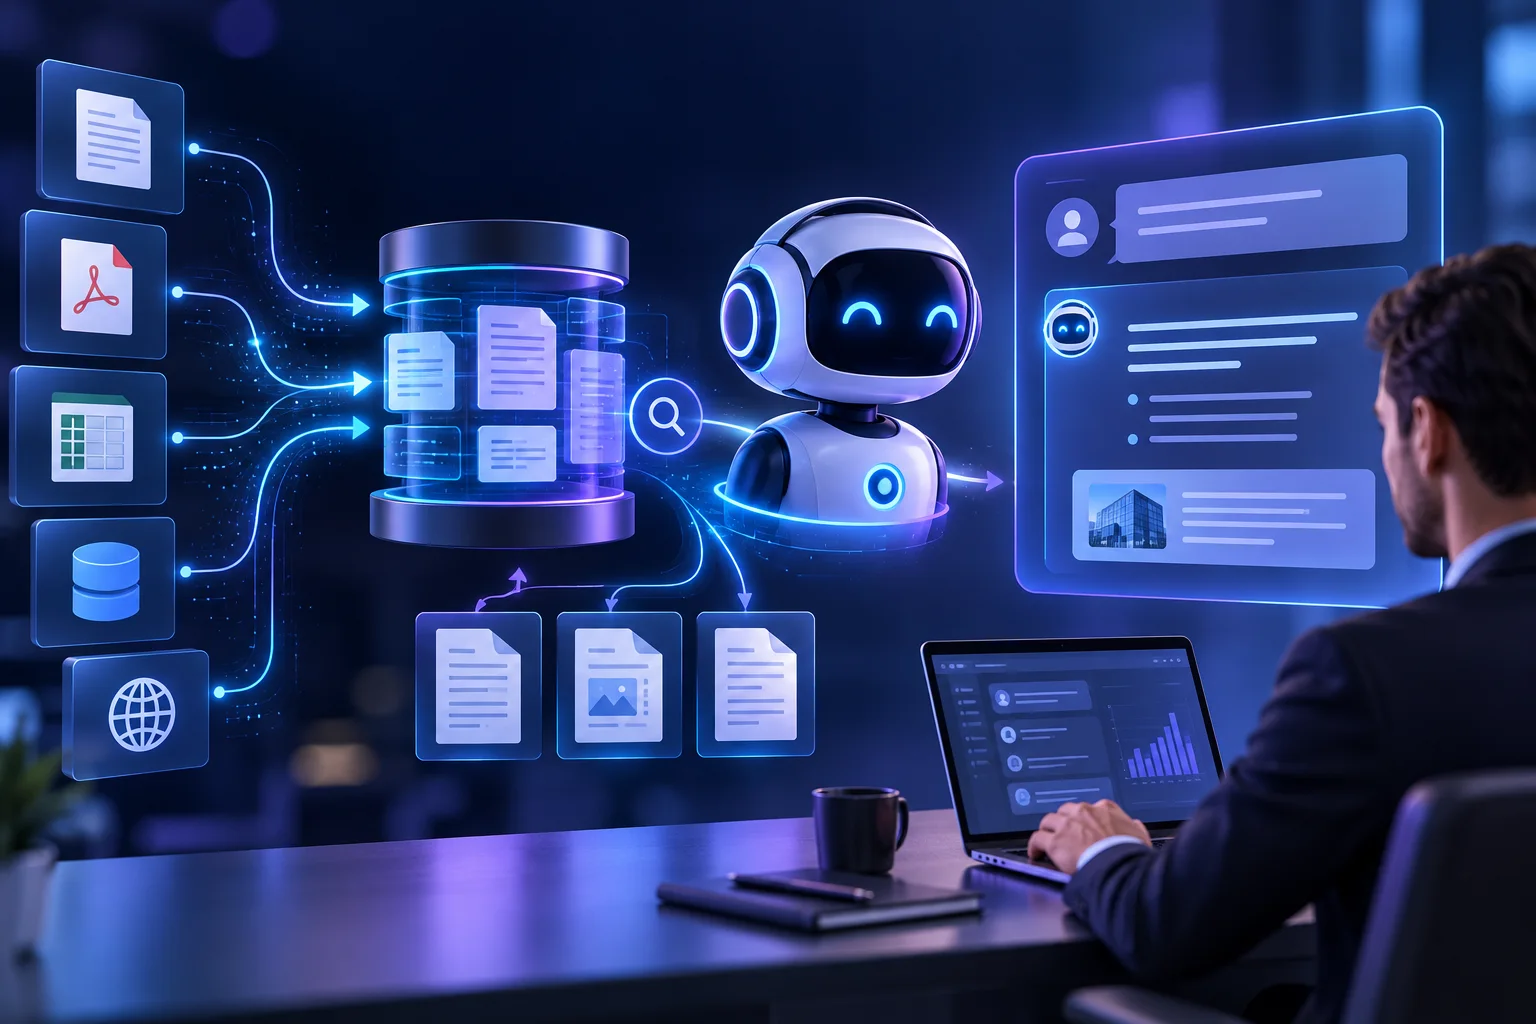
The usual procedure begins with preparation of documents for retrieval. Text data are extracted from the document, structured in such a way that makes searching easy, metadata are generated and the index is created. After the user asks a question, the system searches the index and finds relevant information to the question. Then the model is provided with the question and the evidence.
The output answer must be helpful for the user and make the evidence easily reviewable. If the answer to the question is not in the document, the application must refrain from making a guess and provide the user with a straightforward statement, such as “I cannot find this in the approved documents.”
RAG is different from training the model to remember all your documents. The retrieval process occurs as part of the application flow, and the available evidence may vary as the documents get updated. Amazon Web Services provides an overview of RAG to explain the concept and how it uses external data. Explore RAG overview for related information.
First, clean up your knowledge base
Prepare a list of the documents that your assistant will be using. Include the author of the document, the target audience, the time when the document was last reviewed, and the document’s approval status. Remove any old documents or mark them clearly as being outdated. If you have three conflicting return policies, resolve the conflict before adding them to a vector database.
Find the information included in bad formats. Images, tables, and slides are hard to extract. The row in a table doesn’t make much sense without the header. Don’t assume that all file types supported by your assistant provide good information; test the extraction on a sample set of files.
Document unwritten knowledge where appropriate. When employees have knowledge about exceptions from practice, an assistant who only follows official instructions misses the important point. Decide whether such exceptions need to be documented as guidelines or whether they need to be left to human discretion. The creation of the knowledge base will help to identify process improvement opportunities well in advance of AI.
Maintain context when drafting documents
Documents should preserve enough context such that a sentence within the document makes sense on its own. A sentence regarding the warranty could require additional information about the type of product, date of purchase, and exclusions appearing above it. Failure to maintain such context during document preparation would yield partial information and an answer more general than what the policy permits.
Test retrieval using documents that reflect your organization’s actual work. Use long manuals, FAQs, spreadsheets, and other documents for test preparation. There is no single chunk size for all knowledge bases available. Verify whether the text retrieved contains all the necessary information to consider it a valid response.
Add appropriate metadata, e.g., title of document, section of document, version, effective date, and authorized access groups. The metadata is used both for filtering the results and explanation of the results. It also helps with maintenance if the document is updated or retracted by its owner. The more efficient management of the retrieval system will be if it will be possible to trace the record back to the source.
Do not use access control as part of model judgement
The application should know the identity of the user and the access that they have. Never let the model decide if the private document should be shared based on the statement from the conversation. Saying “I work in finance” is not an authentication method.
Apply the filtering rules before passing the protected data into the model. If a sales worker is unable to see an HR document in the original application, then the assistant must not make this possible via a convenient search mechanism. Think about how permissions updates, departures, and deletions of documents affect indexing.
Carefully test cross-role questions. The same question could be asked by both a manager and a contractor, yet their access must be different. It is necessary to verify whether the assistant delivers only the appropriate data, including in the titles, snippets, logs, and citations. There can be privacy concerns in areas other than the answer itself.
Use citations as a reviewing tool
The citation provides the reader with the evidence, but the evidence will be of use only if it really supports the specific claim. The answer could give the reader the link to the document, which seems to be relevant while making a claim which is not made in that document at all. The evaluation should determine whether the answer sticks to what was said in the cited passage and keeps within its limitations.
Please, provide the titles of the sources and relevant excerpts from them when you can. A citation “Document 147” is more work for the reader than it is required. For instance, the citation “Product Warranty, section 4, reviewed September 2026” is more detailed and clear. Please, don’t forget to make sure that the document provided in the link is available to the user.
When dealing with internal procedures, it would be better to show the appropriate quote next to the answer. It will allow employees to make conclusions about the provided answer. Do not bombard users with the list of sources if only one quotation is needed.
Create an effective refusal and escalation strategy
Assistant must have an effective way to deal with the situation when there is not enough information, information contradicts each other or is not relevant. In this case, it will be able to show all the gathered information, uncertainties and the way to get in touch with the team responsible for this procedure.
The user should not be required to repeat the entire conversation after escalation. If properly managed with the user's consent and appropriate data handling, escalation would include the question along with all the relevant context as well as the reason why the assistant couldn't do it.
Escalations should be reviewed as a means of learning. Persistent unanswered questions might indicate an omission in documentation, confusing product rules, or retrieval problem. In general, solving such issues would yield better results than trying to add yet another instruction for the model to try harder. Ownership for improvement should be assigned.
Evaluate with real questions before launch
The test set is created using sample questions, and their correct answers or correct behavior is approved by the domain experts. Some questions should not have an answer according to the knowledge stored in the knowledge base. There are some outdated words, wrong spellings, short questions, and questions requiring further clarifications. Users do not always ask questions the way the model was trained.
Evaluate the retrieval and answer processes individually. In case the correct source does not get to the model at all, changing the answer prompt will not help in the process. If retrieval gives you the right passage but the answer is wrong, it is an issue with the answer process.
Outcome metrics are equally important. Is it easy for staff to get approved information? Is the user happy with the response? Does the assistant avoid redundant operations without causing a rise in correction times? One technical measure is insufficient to understand if the tool benefits the company. Systematic assessment should be supplemented by observations on a small pilot team.
Prompt injection and unsafe instructions test
There is a possibility that unsafe instructions may occur either in the user request or in the document used by the application. There are instructions in the document that will require the assistant to break some rules or give some information. Treat retrieved documents as evidence, not authority to override application rules or permissions.
Make distinction between replies that do not change the system and actions that modify systems. Explanation of an invoice by an assistant will not fall under the same category as refunding of the invoice. Start with least privileges and then expand them based on requirements. Check validity, permission, and review when required.
OWASP defines excessive agency as a threat where AI applications are given more functions, permissions, or autonomy than required. Its excessive agency guidelines make a good starting point in setting out your boundaries. Get an assessment of the real process from the security professionals, not from the prompt itself. Explore excessive agency guidance for related information.
Data Management Planning
Map the path of information: original source documents, extraction services, indexation, model queries, application logs, and support logs. Identify what information is needed at each stage. Review vendor terms and configurations in conjunction with the appropriate parties. A simple integration might end up making copies of information that was not expected because the behavior of the integration was not well understood.
Determine proper retention period for logs and evaluation. Logs are good for resolving issues, but there might be no need for indefinite storage. Control access and do not log unnecessary data. Redaction needs testing because partial redaction might give wrong impression about security.
Plan the deletion process as a part of the system architecture. What would be the way to delete the source document from the search results, answers stored in cache and created indexes? How would such deletion request by the user be handled? The above mentioned process questions have to be answered prior to building up the knowledge base.
Manage the latency and cost while preserving the quality
Users care about latency. Separate the process into retrieval, model generation, and answer delivery phases in order to identify the phase responsible for delays. Different approaches are required for a slow document retrieval and excessive request size. Profile typical queries and even those which require clarification.
Cost should be estimated based on realistic usage and length of answers. This includes indexing, storing, monitoring, document handling, and other support costs. Model request cost is just one component of the total. Cost per usable conversation or completed task should be tracked, since low cost answers that need correcting aren't necessarily low cost.
Caching is good for selected repeat requests, but requires careful handling. The answer might depend on the user's rights or policy version number. Caching must not pass protected information between users. Caches need to be invalidated or scoped according to the business model.
Pilot in small scale with known owners
Choose a small sample group that represents the target audience and can offer feedback. Determine the limitations and boundaries of the assistant. Make sure that users are able to report an incorrect answer from the tool with ease, and identify the cause for it. Pilot testing should aim to create evidence, rather than simply creating buzz around the tool.
Identify the product owner, knowledge owner, and operational owner. The product owner keeps track of the value, while the knowledge owner confirms the information, and the operational owner handles any problems. A single person may fill different roles in a small organization.
Establish criteria for going live prior to the end of the pilot. For instance, important test questions should work right, access tests should succeed, and support escalation should function. Pick appropriate criteria according to your risks and process. Demonstrating the ability to answer five test questions well is not sufficient justification to go live.
Maintain the assistant post-launch
It is going to be necessary to maintain a RAG assistant because everything in the company changes. Make a plan for how to re-index approved updates and detect any failed imports. The process of uploading a document cannot be completed until the new data is available and the old one does not create confusion anymore.
Check again after implementing a change to the model, retrieval, prompt tuning, or document structure. Improvement of one question could cause issues with another one. It is important to keep the same test set but expand its coverage with negative cases. This way the team will be able to compare different versions easily before releasing them.
Discuss unanswered questions with the domain team. Some require better documentation, some require changes to the user interface, and some aren't appropriate for the assistant at all. Don't try to expand the scope just because you can get a response. The reliability of the product is improved by keeping it simple.
Questions to Ask of an AI Development Partner
Inquire how they will ensure accuracy, handle permissions, source management, and missing data. Request a recommendation for the pilot's scope and any assumptions they have about your documentation. Find out who will maintain the system after implementation and how you will be able to test the knowledge base.
Find out what kind of integrations would be needed for the project. The internal assistant would need something like single sign-on and document permissions whereas a customer assistant might have other needs such as ticket management and product information. Find out whether it will only answer questions or do anything else as well.
Request a transfer that includes data flow, deployment, assessment, monitoring, and incident management. It should be evident who owns the code and credentials. A good project ensures that the company understands the scope of the system and its maintenance capabilities rather than remaining in dependency on a mysterious chatbot interface.
How Digitonix can help
The company provides AI and automation services, software development, and cloud services. The first step during the project concerning the company knowledge assistant will be selecting a use case, looking through approved source documents, setting up access limits, and creating an assessment strategy. AI and automation services can provide you with more information on this matter.
Discuss Python development, PostgreSQL, cloud computing, and DevOps services alongside the implementation plan. The technologies will depend on what type of data and integrations you need, and not only because of marketing purposes. Explore cloud and DevOps services for related information.
Preparations before consulting involve bringing some allowed documents, sample questions, and who might have access to certain information. You can contact Digitonix in order to get information about scoping a pilot and associated tasks needed to build a useful assistant. Explore Contact Digitonix for related information.
Frequently asked questions
Can RAG stop hallucinations?
This may result in evidence that will be relevant but still create the possibility for an erroneous answer. The quality of retrieval, sources, prompt, and behavior of the application have a huge effect on this issue. Check whether the produced answer contains some evidence from the sources and whether the assistant refuses to provide an answer without evidence.
Is fine-tuning of the model needed?
It depends. Retrieval makes it possible to have access to the external knowledge without fine-tuning of the model. Look at the process and cases of failure to know whether there is a place for fine-tuning.
Can the assistant use private company documents?
Perhaps, contingent upon proper authorization, vendor assessment, management of data, and control of access to those data. Show diagrammatically the path that the documents and communications take through this process. Don’t allow any access to unauthorized information by users.
Where do we start?
Select a good process for workflow, clean the approved source data, do some sample testing, and conduct a pilot study. Extend where there is knowledge of errors, required maintenance, and advantages to users.
Written by Digitonix Editorial Team
Specializing in artificial-intelligence-ai, our experts bring years of industry experience to help you navigate complex digital challenges.
View all postsOn This Page

Ready to Build Something Great?
Partner with Digitonix, the leading IT company in Jaipur, for world-class web development, mobile apps, and digital marketing solutions. Join 500+ businesses achieving measurable growth.